
The first sign that an AI team has outgrown ad hoc experimentation is usually not a model failure. It is a sentence in an incident channel: “Which prompt was production using?”
The question sounds simple until the team discovers that a developer edited a prompt in a shared dashboard, the staging service fetched latest, production fetched production, the evaluation dataset had changed since last week, and the trace did not record the commit or prompt version that produced the answer. Everyone has a plausible explanation. Nobody has a reproducible one.
Langfuse is often introduced as a place to inspect traces and compare model outputs. That is useful, but it is not the whole operational problem. A mature AI system needs a release path that connects a prompt or model change to evidence, approval, deployment, observation, and rollback. Langfuse can provide important pieces of that path through prompt versioning, labels, datasets, experiments, scores, tracing, APIs, and CI/CD integrations.
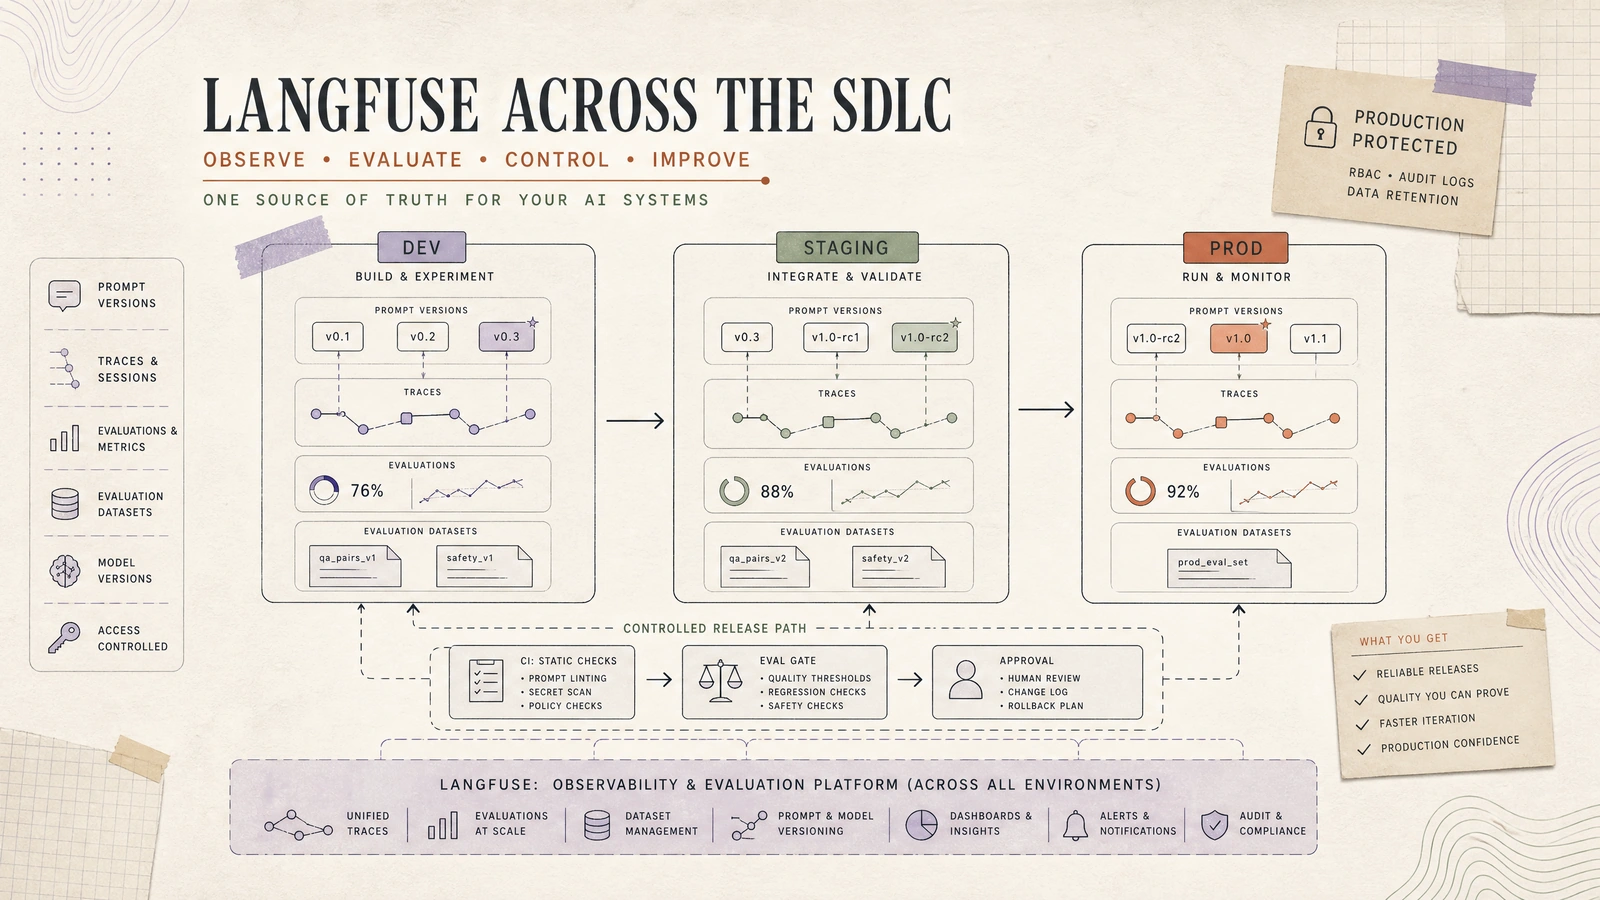
The thesis: Langfuse should not be treated as a production dashboard that sits beside the release system. It should be part of the AI release system, while Git, the application runtime, and the data boundary each remain responsible for the things they are best suited to own.
This article presents a practical operating model for teams that use Langfuse in development and production. It focuses on the synchronization problem: what should move between environments, what should be promoted by reference, what should be redacted or recreated, and what should never be copied. It also shows how to build a CI/CD path that can reject a prompt release before it becomes a production incident.
The environment problem is a control problem
Many teams describe dev, staging, and production as three URLs. That is not enough. An environment is a set of controls around code, secrets, data, model access, prompt versions, trace visibility, and release authority.
A development environment is allowed to change quickly. It may use synthetic or redacted data, experimental prompts, mock tools, and a broad set of debug fields. Production has a different obligation. It must preserve tenant boundaries, limit access to sensitive traces, use approved model and prompt versions, and make its behavior explainable after the fact.
Staging is valuable only when it is a meaningful rehearsal. If staging fetches a different prompt label, uses a different tool schema, or has a different masking policy from production, a green staging run may be evidence about another system.
The goal is not to make every environment identical. The goal is to make every intentional difference explicit.
| Control plane | Development | Staging | Production |
|---|---|---|---|
| Application code | Branch or pull request build | Candidate release commit | Approved immutable release |
| Langfuse project or boundary | Developer or team project | Shared release-validation project or isolated staging project | Production project with restricted RBAC |
| Prompt selection | latest or branch-specific label for exploration |
Candidate version or staging label |
Protected production label or pinned version |
| Dataset | Synthetic, redacted, or curated test data | Versioned regression and edge-case set | Read-only reference; raw production data is not copied by default |
| Credentials | Developer-scoped, low privilege | CI/staging key with limited scope | Production key stored in secret manager |
| Trace payload | Debug-friendly but masked | Full diagnostic fields under controlled access | Minimum necessary payload, aggressive masking and retention |
| Promotion authority | Author or team reviewer | Release owner and evaluation gate | Protected approver or change policy |
Langfuse prompt versions are scoped to a project, and Langfuse documents labels as a mechanism that can represent environments, tenants, or experiments. The latest label points to the newest version, while an explicit production label identifies the version intentionally selected for production. A rollback can be performed by moving the production label to an earlier version; protected labels can restrict who is allowed to change that pointer.
That behavior creates an important design choice. A label is a deployment pointer, not a substitute for release evidence. The application should record the resolved prompt name, version, label, and release identifier in its trace metadata. Otherwise, moving a label later can make historical behavior difficult to reconstruct.
Decide what the source of truth is
The most dangerous synchronization design is one that has two sources of truth without declaring which one wins. A prompt may be edited in Langfuse, copied into a repository, templated again at runtime, and then modified by a feature flag. When an incident happens, the team cannot tell whether the repository, the registry, or the runtime configuration is authoritative.
There are three reasonable ownership patterns.
The first is registry-first. Langfuse owns prompt authoring and versioning. A reviewer creates a new prompt version, attaches a change description, runs an experiment, and moves an environment label after approval. GitHub Actions can be triggered when the prompt changes through the documented Repository Dispatch integration. This is convenient for teams whose prompt editors work primarily in Langfuse, but it requires strong webhook security and an audit rule that prevents undocumented production edits.
The second is Git-first. Prompt templates, configuration, and evaluation definitions live in a repository. CI validates and publishes a new Langfuse prompt version. Langfuse becomes the runtime registry and observation surface, while Git remains the reviewable source of change. This model is attractive when prompts are tightly coupled to application code or must pass the same pull-request process as code.
The third is hybrid ownership. Stable prompt content and test fixtures are reviewed in Git, while Langfuse labels, experiment runs, scores, and production observations remain in Langfuse. The CI pipeline publishes an immutable version and records the resulting Langfuse version ID in a release manifest. Product or operations teams may use Langfuse to compare versions, but only the promotion workflow can move the protected production label.
The hybrid model is often the most practical because it separates content review from runtime assignment. The specific recommendation is less important than the contract:
Git owns:
  prompt source, application code, schemas, evaluator code, release manifest

Langfuse owns:
  prompt versions, labels, traces, observations, scores, experiment records

The promotion workflow owns:
  which tested version receives the staging or production label
Do not silently synchronize both ways. If a Langfuse webhook commits to Git and a Git workflow publishes back to Langfuse, define a loop-prevention field and an ownership rule. Otherwise, a single edit can generate a webhook, a commit, a CI run, another prompt version, and a second webhook that appears to be an independent change.
Treat prompt versions as release artifacts
A prompt is not only a string. It is a runtime artifact with a name, type, version, model configuration, variable contract, tool assumptions, evaluator expectations, and operational owner.
A useful release manifest can be small enough to review in a pull request:
release:
  id: support-agent-2026-02-24.1
  git_sha: 8f31c2a
  application_version: 2026.02.24.1
  owner: ai-platform
  change_type: prompt

langfuse:
  project: support-production
  prompt_name: support/answer
  prompt_version: 27
  staging_label: staging
  production_label: production

model:
  provider: approved-provider
  name: approved-model-alias
  parameters:
    temperature: 0.2
    max_tokens: 900

evaluation:
  dataset: regression/support-golden
  dataset_version: 2026-02-21T09:15:00Z
  experiment: support-agent-2026-02-24.1
  gates:
    correctness: ">= 0.90"
    policy_violation: "<= 0.01"
    p95_latency_ms: "<= 2500"

rollback:
  previous_prompt_version: 26
  previous_application_version: 2026.02.17.2
The manifest is not intended to duplicate every trace. It is a compact statement of what the release is supposed to use and what evidence allowed it to proceed. At runtime, the trace should carry the manifest ID or release ID, while the manifest links back to the exact prompt and dataset versions.
When an application fetches a prompt by label, use the Langfuse SDK retrieval path that supports client-side caching, retries, and fallbacks rather than rebuilding the retrieval logic around a raw request. In production, prefer an explicit environment label or resolved version. Use latest for exploration, not as an unreviewed production dependency.
A safe fetch contract looks like this:
resolve prompt:
  name = support/answer
  label = production

record in trace:
  prompt_name = support/answer
  prompt_version = resolved_version
  prompt_label = production
  release_id = support-agent-2026-02-24.1
  git_sha = 8f31c2a
If the registry is temporarily unavailable, the fallback must also be observable. A cached prompt can be a valuable availability mechanism, but a trace should reveal that the application used a cached or bundled version rather than implying that it resolved the current production label.
Sync projects without copying the wrong data
Langfuse recommends a single deployment in many self-hosted scenarios, using organizations, projects, and RBAC for logical separation. Multiple deployments can be justified by strict regulatory or infrastructure requirements, but they increase operational cost and make prompt and dataset synchronization more difficult.
A team should therefore choose a boundary deliberately. A single deployment with separate projects may be sufficient for dev, staging, and production when access controls, network policy, and retention are appropriate. Separate instances may be necessary when production data must remain in a different network or jurisdiction, or when a compliance policy requires physical separation.
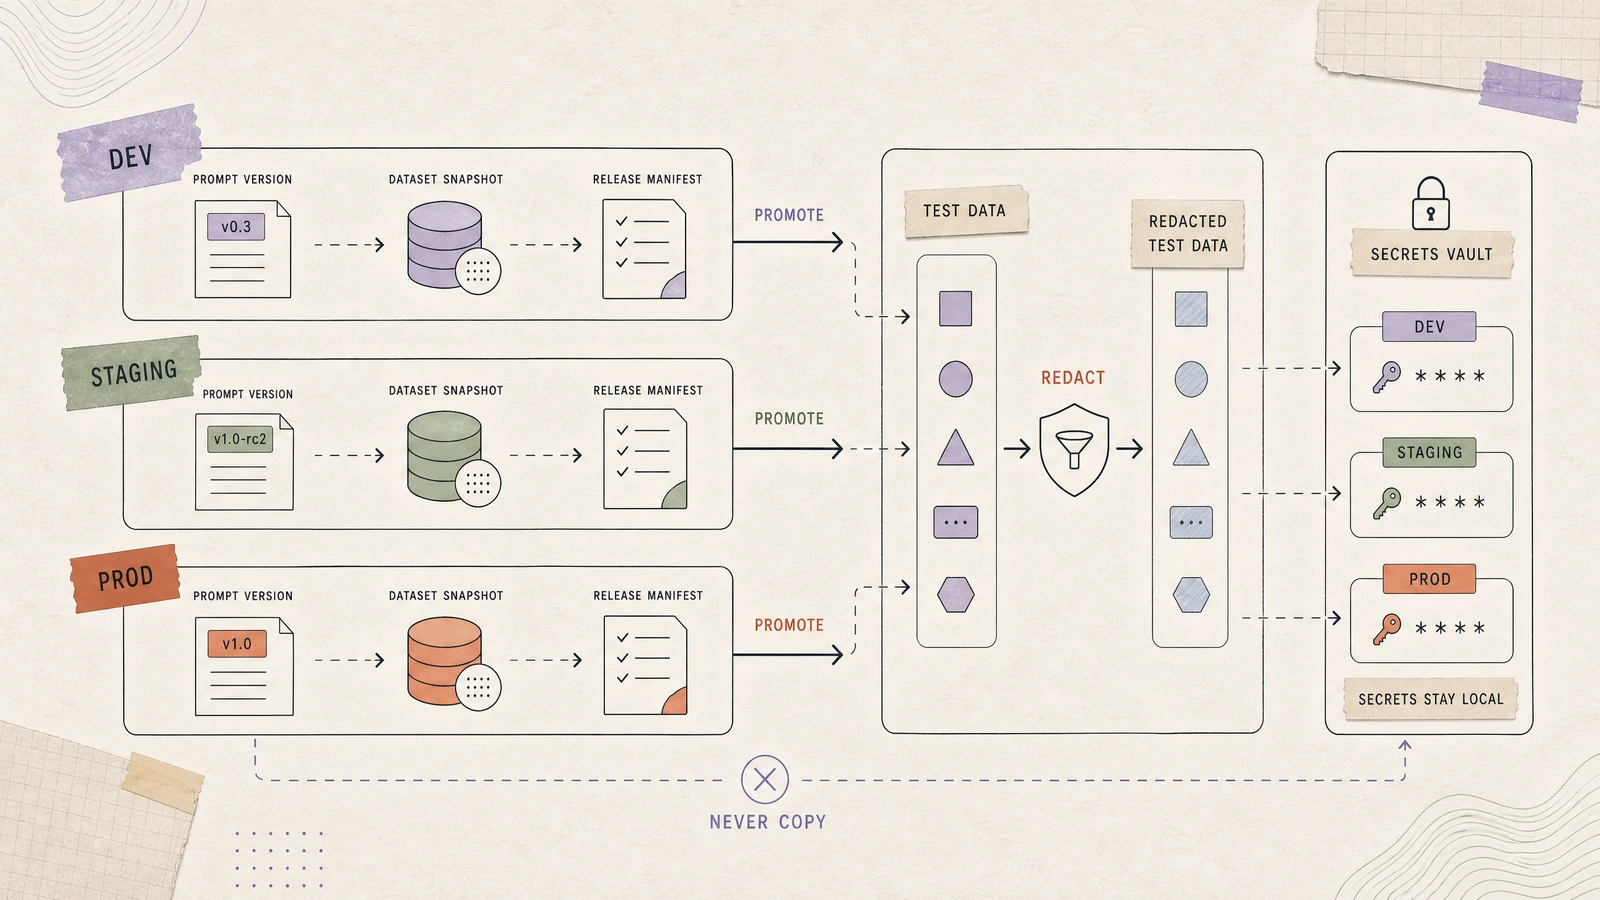
Project separation also affects prompt movement. Because prompts are scoped to a project, a prompt version cannot be assumed to exist in another project merely because the names match. Promotion between projects should use an explicit export/import or publish step that records the source version, destination version, checksum, and actor.
Use this synchronization policy:
| Object | Sync strategy | Why |
|---|---|---|
| Prompt source | Promote through Git or a controlled Langfuse API workflow | Reviewable and reproducible |
| Prompt version ID | Record as source metadata; do not assume IDs match across projects | Project scope can produce different destination IDs |
| Prompt label | Move only through an approved promotion action | A label is a deployment pointer |
| Dataset definition | Version and promote a selected snapshot | Dataset item changes create new versions |
| Synthetic test items | Copy or recreate | Safe for CI and portable across boundaries |
| Production traces | Query selectively, redact, and turn into approved cases | Raw traces may contain sensitive data |
| Production secrets | Never copy | Credentials are environment-specific |
| Scores and experiment results | Export summary or reproduce against a declared dataset version | Avoid confusing evidence from different data states |
Langfuse dataset changes create versions tracked by timestamps, and a dataset can be retrieved at a specific version for reproducible experiments. This is particularly useful when a team wants to explain why a prompt passed in February but fails when rerun against a later dataset with new edge cases.
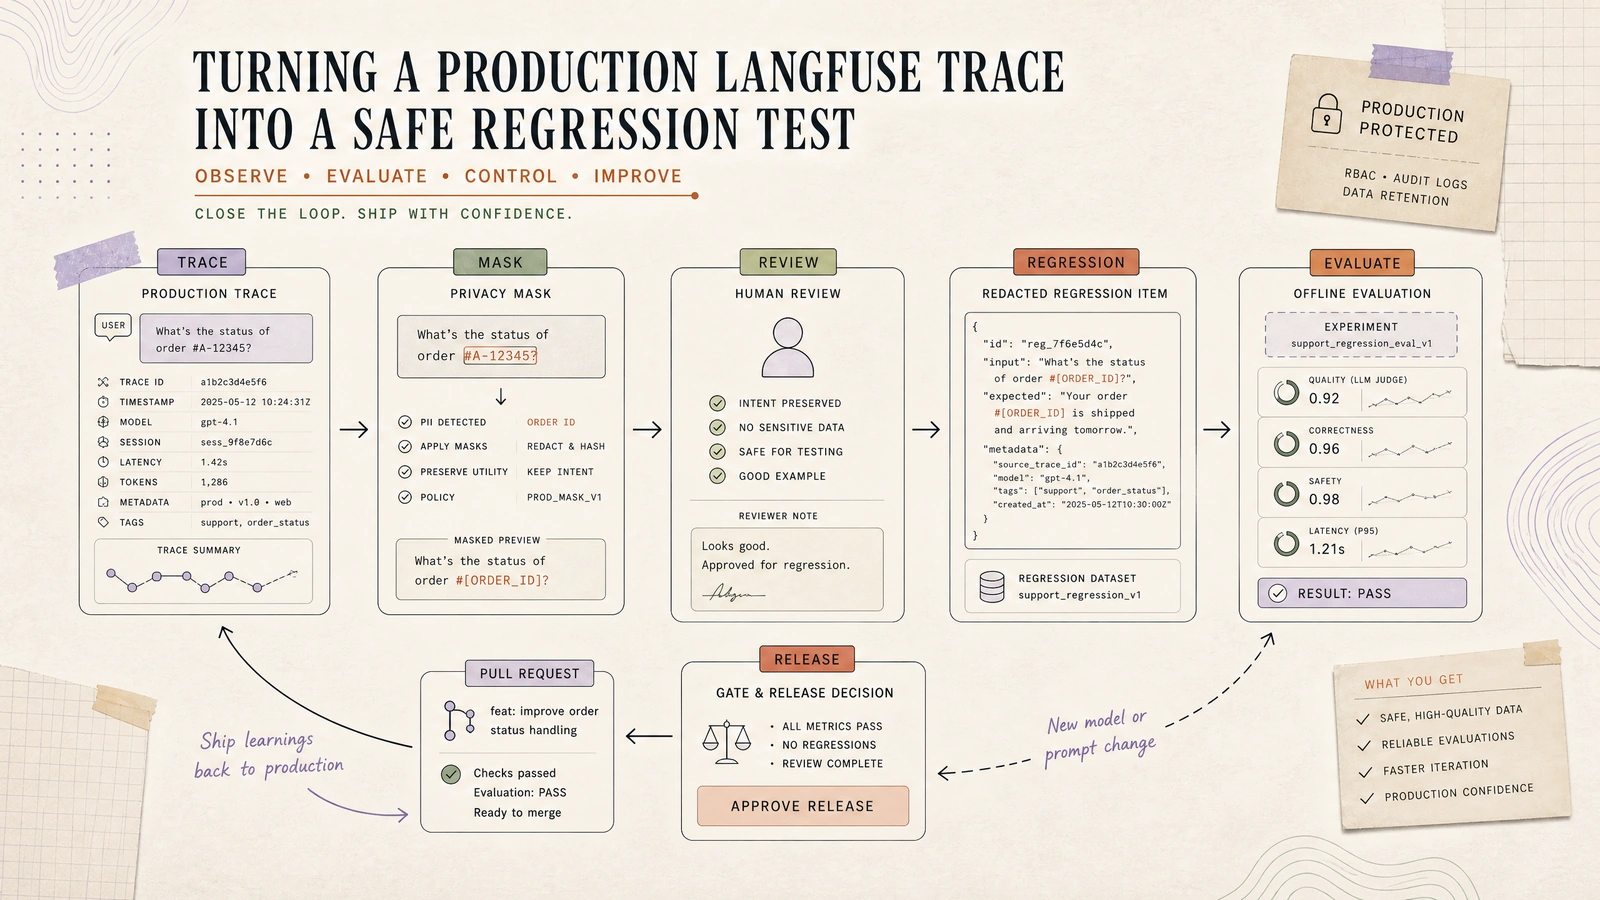
Do not use production as the default training ground for development. Instead, establish a controlled path from production observation to a redacted regression item. The path should include data owner approval, PII checks, tenant authorization, and a record of why the example is needed. A production trace is evidence, not automatically a permitted test fixture.
Build a trace contract before adding more dashboards
A trace is most useful when it answers the questions that an incident responder or evaluator will ask later. More fields do not automatically make a trace better. A good trace has a stable identity, a meaningful hierarchy, clear input/output boundaries, and enough release context to reproduce the path.
For a production AI workflow, standardize a small set of fields:
trace_id
session_id
request_id
tenant_id_hash
workflow_name
workflow_version
environment
release_id
git_sha
prompt_name
prompt_version
prompt_label
model_provider
model_name
tool_schema_version
evaluation_dataset_version
sampling_policy
masking_policy
The values should be application-controlled and consistent across services. A gateway can create the request and trace identity, while child generations and tool spans inherit the release and workflow context. Tenant identifiers should be opaque or hashed according to the data policy; do not put a raw customer email into a trace just because it is convenient to search.
A trace contract also needs a negative definition. Specify fields that must not be recorded: access tokens, full payment details, private keys, unredacted health information, and raw secrets embedded in tool responses. The application should avoid creating those attributes in the first place whenever possible.
Langfuse supports masking of trace inputs, outputs, metadata, and OpenTelemetry attributes before export. For current Python SDK setups, the documentation recommends mask_otel_spans for export-stage masking, while other SDK and OpenTelemetry configurations have their own hooks. Masking functions should be deterministic and fast. A masking implementation that blocks export or fails open unexpectedly can create a false sense of safety.
In self-hosted deployments, Langfuse documents both client-side masking and server-side ingestion masking. Client-side masking is the boundary to use when data must never leave the application. Server-side masking can act as a centralized safety net, but it may be an Enterprise feature and does not replace client-side protection.
The trace should also record the masking policy version. A later investigator should be able to distinguish “the answer was wrong” from “the evaluator could not see the redacted evidence.” Observability and privacy are not separate projects; the trace contract is where they meet.
Use datasets as release tests, not a screenshot gallery
A dataset is valuable when it is treated as a maintained test suite. A collection of impressive examples is not enough. It should contain representative inputs, expected outputs or evaluation criteria, edge cases, negative cases, policy-sensitive cases, and examples from prior incidents.
Organize datasets by purpose rather than by whoever created them:
| Dataset family | Purpose | Typical gate |
|---|---|---|
| Golden | Stable representative cases | Correctness and required behavior |
| Safety | Refusal, privacy, policy and tool-boundary cases | Violation rate and escalation behavior |
| Regression | Incidents and previously fixed failures | No reintroduction of known failure |
| Performance | Long context, concurrency and expensive paths | Latency, tokens and cost |
| Adversarial | Ambiguous, conflicting or manipulative inputs | Robustness and abstention |
The dataset name should make its contract visible. support/golden is less informative than support/golden/v3 if the team does not define whether the suffix is a semantic release, a dataset folder, or an application version. Langfuse supports folders through slash-delimited dataset names, while dataset item changes create timestamped versions.
For each CI run, record the dataset name and exact version timestamp. If the CI job fetches “the latest dataset,” the result is not reproducible: a teammate can rerun the same commit a day later against a different test set and receive a different gate outcome.
Evaluation should compare more than one score. A prompt may improve helpfulness while increasing unsupported claims. It may reduce token cost while increasing escalation. A release gate should therefore define a minimum quality score, a maximum safety violation rate, a latency budget, and a failure condition for missing or malformed traces.
Use a gate table that is specific enough to fail a build:
correctness_score >= 0.90
safety_violation_rate <= 0.01
required_citation_rate >= 0.95
p95_latency_ms <= 2500
trace_completeness >= 0.98
missing_prompt_version = 0
These thresholds are examples, not universal defaults. The team must calibrate them against human labels and business risk. A score from an automated evaluator is evidence with uncertainty, not a license to ignore a critical failure.
Langfuse experiments can be run through SDK workflows on local or hosted datasets, and the versioned dataset capability makes it possible to compare a candidate against a known data state. The CI system should store the experiment identifier, evaluator code version, model used by the evaluator, and summary results in the release record.
The CI/CD pipeline should promote evidence
A prompt change should pass through the same kind of discipline as a code change, but the tests are different. Syntax validation catches malformed variables. Contract tests catch missing tool fields. Dataset evaluation catches quality regressions. Staging smoke tests catch integration failures. Production canary monitoring catches behavior that offline data did not represent.
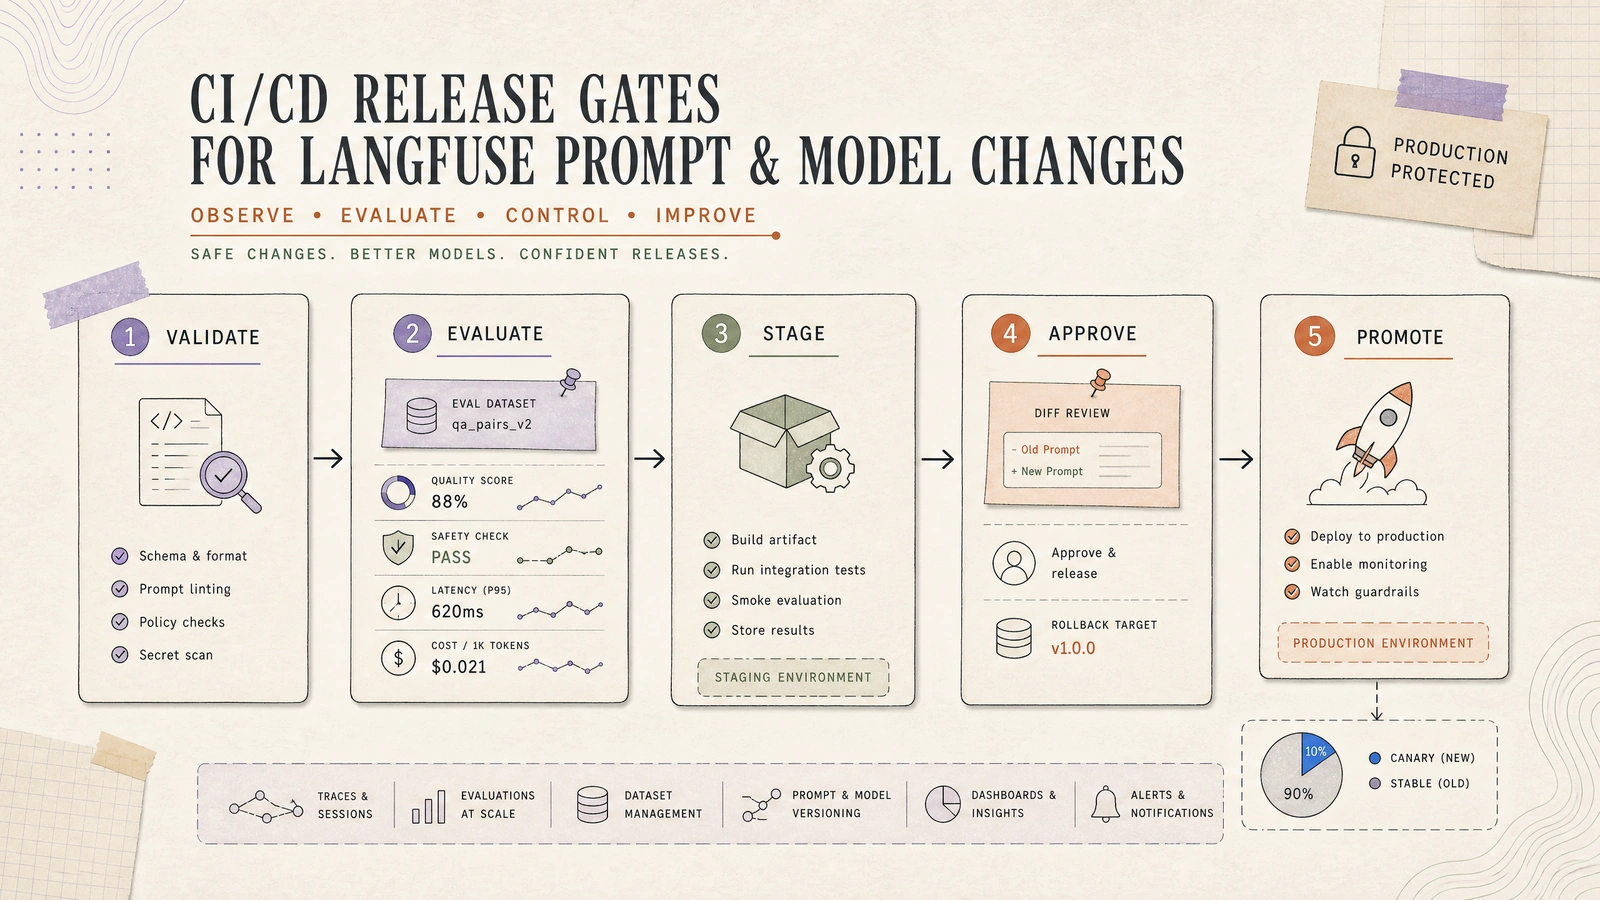
A practical pipeline has five gates:
1. Validate
   prompt variables, schema, policy metadata, required ownership

2. Evaluate
   pinned Langfuse dataset version, regression and safety experiments

3. Stage
   publish candidate, attach staging label, deploy application release

4. Approve
   inspect score, latency, cost, traces and change diff

5. Promote
   move protected production label, canary, monitor, rollback if needed
Langfuse documents two GitHub integration patterns: Repository Dispatch can trigger a workflow when a prompt changes, while Prompt Version Webhooks can synchronize prompt versions into a repository through a webhook server. These are integration primitives, not a complete release policy. The workflow still needs signature verification, idempotency, least-privilege credentials, dataset pinning, and a rule for what happens when CI fails.
A minimal GitHub Actions shape might look like this:
name: AI release gate

on:
  pull_request:
    paths:
      - "prompts/**"
      - "evaluators/**"
      - "release-manifest.yaml"
  repository_dispatch:
    types: [langfuse-prompt-update]

jobs:
  validate:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - run: ./ci/validate-prompts.sh
      - run: ./ci/check-release-manifest.sh

  evaluate:
    needs: validate
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - run: ./ci/run-langfuse-experiment.sh
      - run: ./ci/check-evaluation-gates.sh results.json

  stage:
    needs: evaluate
    if: github.event_name == 'push' || github.event_name == 'repository_dispatch'
    runs-on: ubuntu-latest
    steps:
      - run: ./ci/publish-candidate.sh
      - run: ./ci/smoke-test-staging.sh

  promote:
    needs: stage
    environment: production-approval
    runs-on: ubuntu-latest
    steps:
      - run: ./ci/promote-production-label.sh
      - run: ./ci/start-canary.sh
The commands are intentionally placeholders. A production implementation should call the documented Langfuse API or CLI and validate the response against the API reference rather than assuming an endpoint or field name.
A workflow should never print LANGFUSE_SECRET_KEY, prompt contents containing customer data, or raw webhook payloads into public CI logs. Use separate project-scoped keys for the environments, store them in the CI secret manager, and grant only the operations the job needs. The Langfuse CLI uses the same project API key pair as the SDK/public API and supports a region-specific or self-hosted base URL through environment variables.
Promotion is a state transition
The most reliable promotion process does not copy “whatever is currently latest.” It moves a known version through explicit states.
candidate v27
    ↓ offline evaluation passed
staging v27
    ↓ smoke trace and approval passed
production v27
    ↓ canary monitoring passed
stable v27
The state transition should be idempotent. If a CI job retries after a network timeout, it should not create an ambiguous second release or move production to a different version than the approver reviewed. Use the release ID and source checksum as a deduplication key in the promotion service or workflow.
A release approval should include the diff, not just the score. Reviewers need to see which prompt variables changed, whether the tool contract changed, which model parameters changed, which dataset version was used, how the candidate compares with the current production version, and what the rollback target is.
Protected production labels are useful because they turn a convention into a permission boundary. The label should be movable by the release identity and approved operators, not by every developer who can edit a prompt.
Rollback is a label move plus an application check
A prompt rollback is not complete when the label changes. The running application may cache the prior value, hold a new value in memory, or use a bundled fallback because the registry was unavailable. The rollback procedure must therefore verify the runtime path.
A safe rollback sequence is:
1. Freeze further promotion.
2. Move the protected production label to the known-good prompt version.
3. Verify the application resolves that version in a fresh process.
4. Confirm new traces report the rollback release ID and prompt version.
5. Monitor quality, safety, latency, and error rate.
6. Preserve the failed release and create a regression case.
The failed release should not be deleted merely because it is unsafe. Its trace samples, evaluation result, prompt diff, and incident context are useful evidence. Deletion destroys the history needed to understand why the change was promoted.
Rollback also needs compatibility checks. If a prompt version expects a new variable or tool schema, moving only the label may replace one incident with another. The release manifest should declare application compatibility and the rollback command should verify that the previous prompt can run with the currently deployed code.
Trace production behavior back to the pull request
A production trace is operationally valuable when it can be joined to the release manifest and then to the change that produced it.
trace_id
  → release_id
      → git_sha
          → pull request
              → prompt diff
                  → dataset version
                      → experiment result
The join can be implemented through trace metadata, deployment annotations, a release table, or all three. The important property is not the storage location; it is that an investigator does not need to infer the release from a timestamp.
If a user reports a bad answer, the first response should be to capture the trace and freeze its context. Then ask whether the prompt version, model, retrieval state, tool response, masking policy, and application release are known. If one of those is missing, the observability gap becomes a new engineering task.
Turn the incident into a dataset item only after the data boundary is reviewed. Redact or transform the input, preserve the failure property, define an expected behavior, and assign an owner. A regression item that no longer represents the original failure is worse than no item because it creates false confidence.
Common failure modes
The first failure mode is using latest in production. It removes the approval boundary and makes a dashboard edit a deployment action. Use an explicit label or version and record the resolved result.
The second is sharing one API key across all environments. It weakens attribution, makes accidental writes likely, and complicates rotation. Use project-scoped keys with environment-specific permissions.
The third is copying production traces into dev without a policy. This can leak PII and customer-specific context. Build a redaction and approval path instead.
The fourth is running evaluations against a moving dataset. The CI result becomes difficult to reproduce. Pin the dataset version and retain the experiment metadata.
The fifth is treating a score as the release decision. A score can hide a safety regression, a latency increase, or a missing trace. Combine quality, safety, performance, completeness, and cost checks.
The sixth is assuming a label move is a complete rollback. Verify caches, application compatibility, fresh traces, and runtime resolution.
The seventh is building a bidirectional sync loop. If Langfuse writes to Git and Git writes to Langfuse without a clear ownership rule, one change can multiply into several versions. Add loop prevention and make one system authoritative for each artifact.
The eighth is masking only in the dashboard. Data that should never leave the application must be masked before export. A viewer permission cannot undo an unsafe ingestion boundary.
A rollout plan for a small team
A small team does not need to implement every control on day one. It needs to establish the order in which controls become non-negotiable.
During the first iteration, separate project keys, add environment, release_id, git_sha, prompt name, resolved prompt version, and model name to every trace. Stop using latest in production. Create one golden dataset and one regression dataset, then pin their versions in CI.
During the second iteration, make prompt changes reviewable. Choose Git-first, registry-first, or hybrid ownership. Add a release manifest, an offline evaluation gate, and a staging smoke test. Protect the production label and write a rollback procedure that someone other than the original author can execute.
During the third iteration, add redacted production-to-regression workflows, canary monitoring, cost and latency gates, and a trace completeness check. Move shared deployment logic into a reusable workflow or release service. Review who can read production traces and who can modify prompts.
The objective is not bureaucratic ceremony. It is to make a small, fast change safer than an undocumented dashboard edit.
Operational checklist
Before merging a prompt or model change, the team should be able to answer the following in the pull request:
| Question | Evidence |
|---|---|
| What changed? | Prompt diff, model/config diff, tool/schema diff |
| Which version will run? | Release manifest with prompt version or controlled label |
| What was evaluated? | Dataset name and exact version timestamp |
| What passed? | Quality, safety, latency, completeness and cost results |
| What data was used? | Synthetic, redacted or approved production-derived cases |
| Who approved promotion? | Protected environment approval and audit record |
| How do we roll back? | Known-good prompt/application version and compatibility check |
| How will we know it is live? | Fresh production trace containing release metadata |
After deployment, the team should inspect whether the runtime is emitting the fields promised by the trace contract. A release that passes offline evaluation but emits no prompt version in production is not fully observable; it is only partially shipped.
Conclusion
Using Langfuse across environments is not primarily a synchronization task. It is a question of authority, reproducibility, and controlled state transitions.
Prompts need versions and protected deployment labels. Datasets need snapshots that can be retrieved and rerun. Traces need release metadata and a deliberate privacy boundary. CI/CD needs to promote evidence rather than a mutable pointer. Production incidents need a path back to a redacted regression case and a pull request. Rollback needs a runtime verification step, not only a label update.
The strongest setup is usually the least magical one: Git records the change, Langfuse records versions and behavior, CI records the decision, and production traces prove what actually ran. Once those boundaries are explicit, Langfuse becomes more than a place to inspect failures. It becomes a reliable part of the release discipline for AI systems.
References
[1] Langfuse — Prompt Version Control
[2] Langfuse — Datasets and Versioned Experiments
[3] Langfuse — GitHub Integration for Prompts
[4] Langfuse — Masking Sensitive LLM Data
[5] Langfuse — Data Masking for Self-Hosted Deployments
[7] Langfuse — Deployment Strategies for Self-Hosted Environments
Comments (0)