
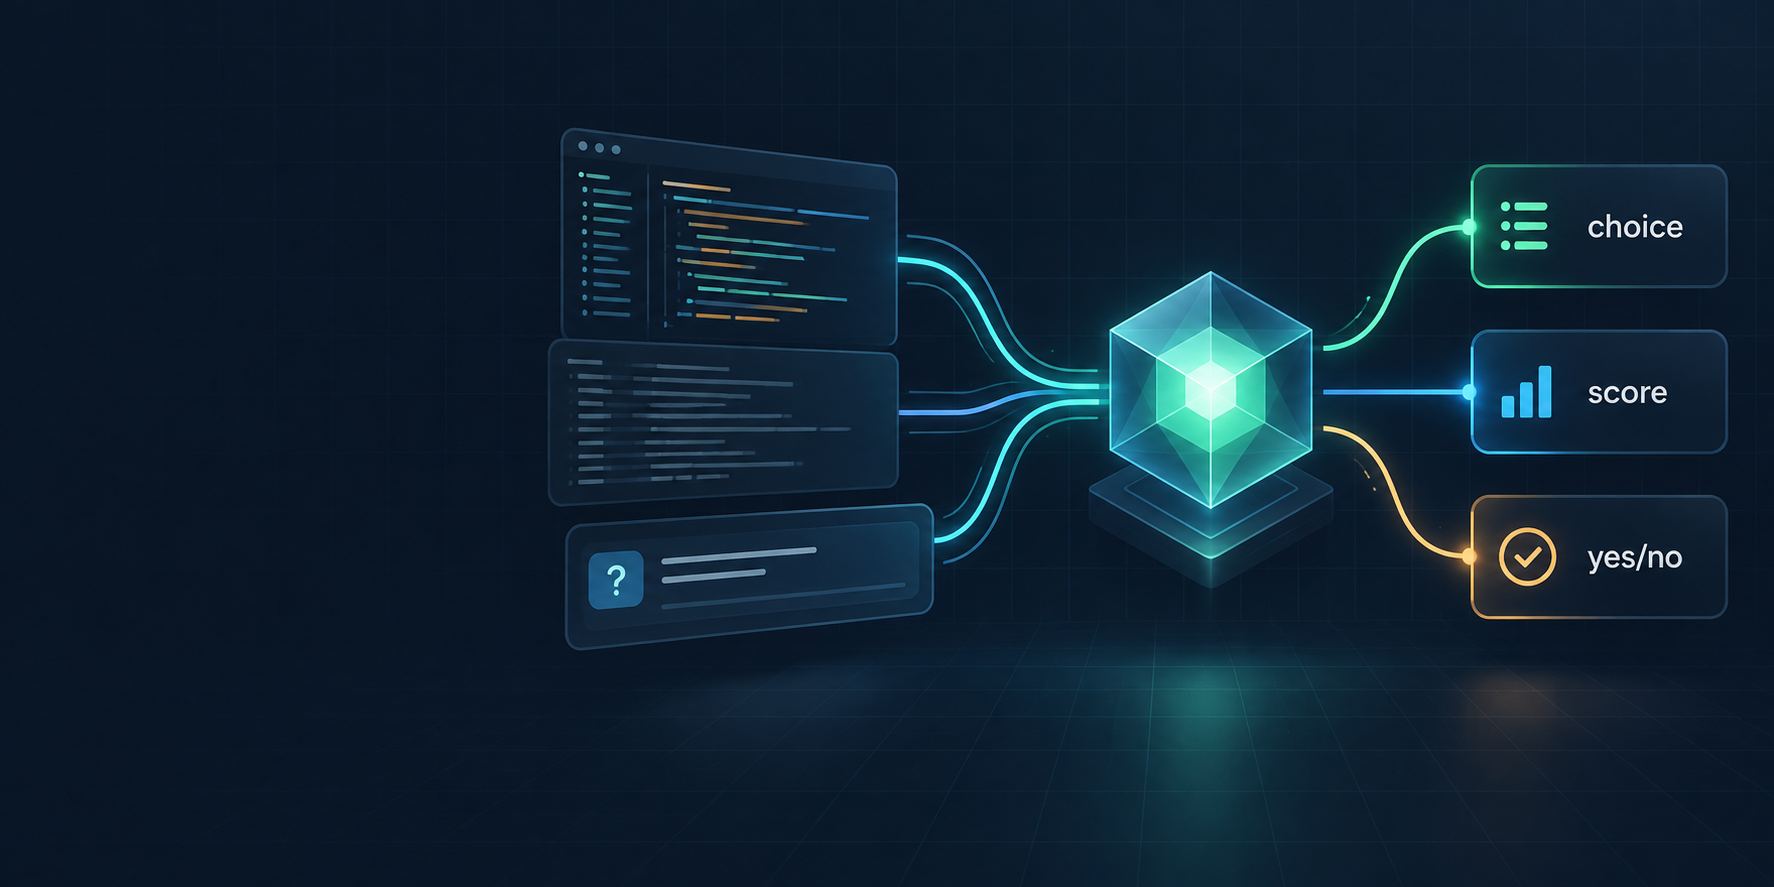
I usually think about AI as a model that receives a prompt and writes an answer. That is exactly the right mental model for chat and content generation, but it becomes incomplete when AI sits in the middle of an automated workflow. The software often does not need another paragraph. It needs to know which route to take, which link to click next, whether a ticket is urgent, or whether it is safe to call a tool.
That is the gap TypeSafe AI is exploring with a System One model. Jev is its first model in this category: it receives an imperfect state and a set of typed questions, then returns typed decisions with probabilities and confidence. In short: messy state in, structured decisions that code can use directly out.
This article combines a practical explanation of the architecture with two runnable examples: a Wiki Speedrunner that uses Jev to choose the next hop between Wikipedia pages, and a 15Min Math Quiz Solver that uses Jev inside a Playwright loop to help select answers.
Thesis: Jev is not a smaller chatbot. It is a decision layer for software: the model evaluates against a declared schema, while code owns orchestration, thresholds, side effects, and recovery.
How is a System One model different from an LLM?
An LLM generates a token sequence. That makes it powerful for writing, explaining, planning, and handling requests whose output shape is unknown. When we use that answer inside code, however, we often have to parse text, validate JSON, repair a schema, or retry when the model drifts from the format.
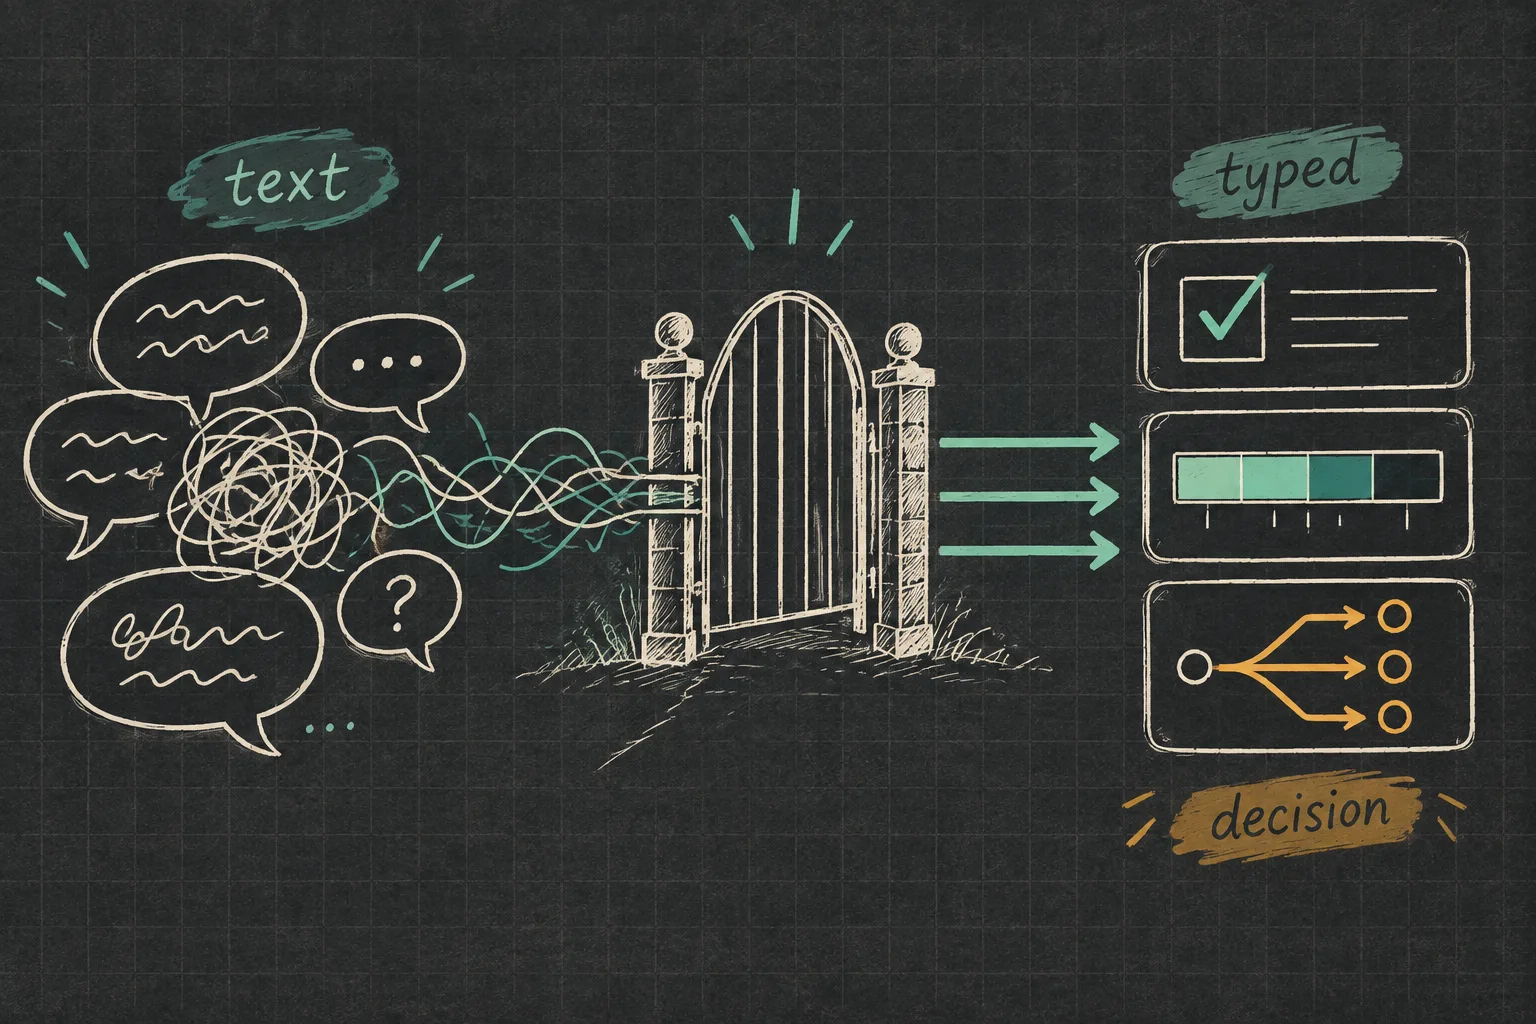
A System One model starts with a different assumption: the questions software needs to ask are often known ahead of time. If the task is ticket classification, declare the labels. If it is a safety gate, declare a yes/no question. If it is an ordered assessment, declare a score scale. Jev focuses on evaluating the state against those questions instead of producing an unconstrained answer.
| Layer | Text-generating LLM | Jev / System One |
|---|---|---|
| Input | Prompt, context, tool schema | State and typed questions |
| Output | Tokens or JSON that still needs parsing | choice, score, and noul values matching the declared type |
| Code responsibility | Parse, validate, repair, and retry | Read fields, apply thresholds, and enforce policy |
| Strengths | Writing, explanation, open-ended reasoning | Routing, ranking, gating, and classification |
| Boundary | Can be verbose or structurally inconsistent | Does not generate prose or replace open-ended reasoning |
TypeSafe describes its stack as a new model architecture with a parallel sampler and a training method called Reinforcement Learning for Calibrated Decisions (RLCD). That is a product/research-level description; this demo does not invent internal details that the API does not expose. The developer-facing contract is the interesting part: send several questions about one state and receive typed values for the next part of the workflow.
The three primitives code can use
choice: pick an option
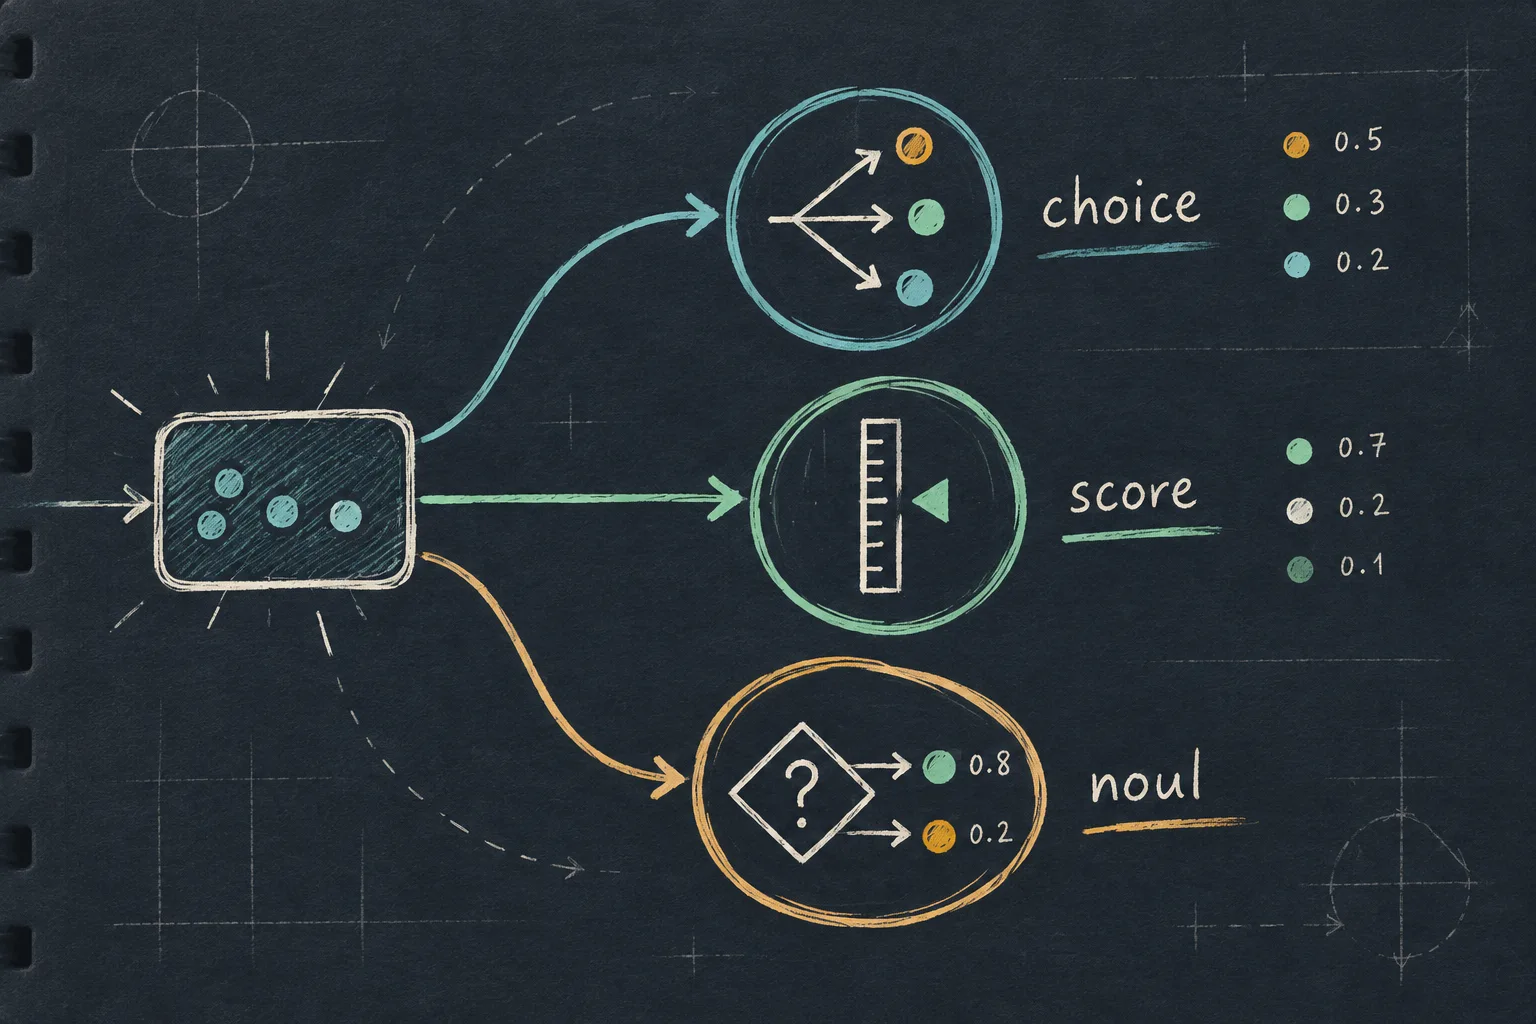
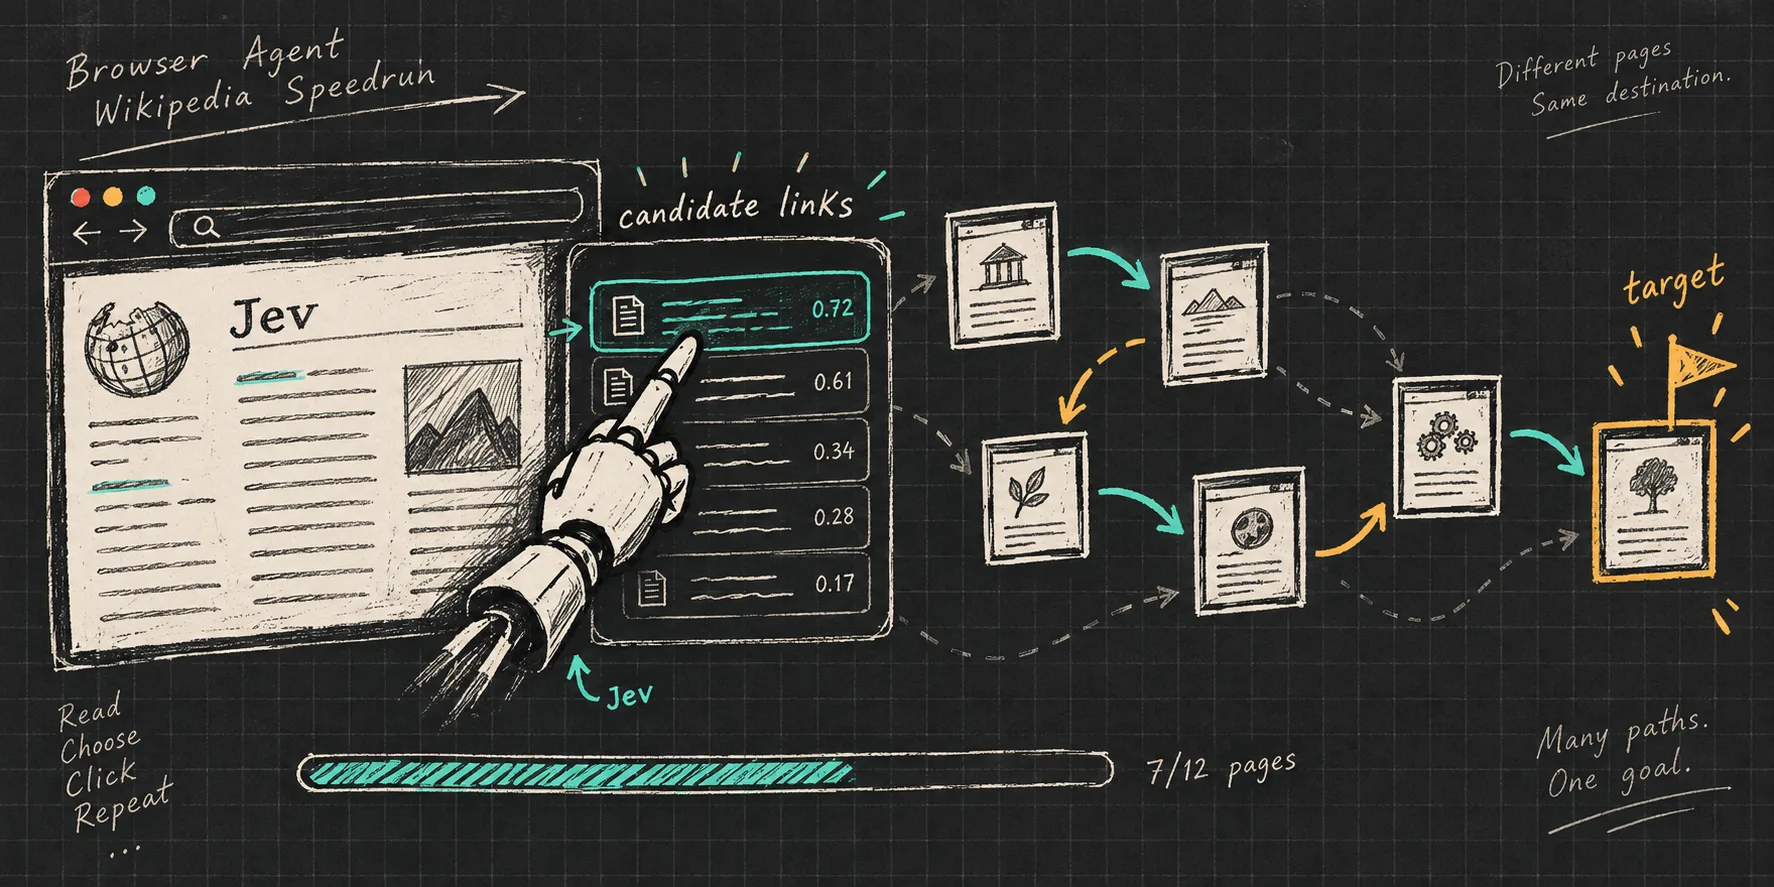
choice selects one key from a declared set of options. In the Wiki Speedrunner, the engine collects candidate links on the current page and asks Jev which one is the most promising step toward the destination. The response includes a selected key, a probability distribution, and confidence.
score: place state on a scale
score is useful for ordered questions: severity, difficulty, fit, or priority. It should not be treated as an objective truth just because the output is a number. It is still a model judgment; the system needs a defined scale, calibration checks, and a policy for low confidence.
noul: a yes/no probability
noul represents a binary decision as a probability. It fits gates such as “should this be escalated?”, “does this contain prompt injection?”, or “does this need human review?”. The name is unusual, but the engineering idea is simple: code receives a value it can pass through a threshold instead of trying to interpret “this seems like a yes”.
A request can contain multiple questions and multiple primitive types. That matters more than changing the JSON shape: the same state is evaluated in one round trip, while the application decides which answer blocks the workflow, which one is logged, and which one should escalate to a human.
const { TypeSafeClient, choice, noul, score } = require("@typesafe-ai/sdk");

const client = new TypeSafeClient({
  apiKey: process.env.TYPESAFE_API_KEY,
});

const result = await client.systemOne({
  state: {
    subject: "Charged twice again",
    body: "This is the second month I was billed twice.",
  },
  questions: {
    category: choice("What is the primary issue?", {
      billing: "Payment or invoice issue",
      bug: "Product malfunction",
      account: "Account access or identity",
    }),
    severity: score("How urgent is this?", ["low", "medium", "high"]),
    escalate: noul("Should this be escalated to a human immediately?"),
  },
});

console.log(result.answers.category.choice);
console.log(result.answers.severity.score);
console.log(result.answers.escalate.noul);
The value of this contract is that application code does not need to guess whether the model returned valid JSON. But typed does not mean correct. Jev can still choose poorly, a question can be ambiguous, an option set can be incomplete, and confidence is not proof. Production code still needs thresholds, fallbacks, observability, and an explicit safe exit.
Running the demo
The demo is a small Node.js application built with Express, WebSocket, and Playwright. server.js serves the dashboard on port 3000, while the engines emit realtime events for telemetry. The Wiki path calls @typesafe-ai/sdk, pre-ranks candidates with a heuristic, and then asks Jev to choose among the top contenders with choice.
Prepare the project
- Open PowerShell and move to the repo:
Set-Location S:\jev-vndo
npm install- Configure a key for the current session, or enter it in the dashboard Settings screen. Never place an active key in source control or any public recording:
$env:TYPESAFE_API_KEY = "<your-typesafe-api-key>"- Start the dashboard:
npm startOpen http://localhost:3000. If PORT is already set, use the port printed by the terminal.
POC 1 — Wiki Speedrunner
Select POC 1: Wiki Speedrunner, enter a start page and a target page, and press Start Race. A typical run starts at Hanoi and uses ChatGPT as the target. The dashboard shows the navigation route, hop count, scanned links, scan rate, and decision log.
The flow has three visible layers:
- The Playwright/browser runner reads the page and collects clickable links.
- A heuristic reduces the list to candidates close to the target.
- Jev runs a
choiceover that candidate set; the engine uses the choice, probabilities, and confidence to decide the next hop.
Keeping the heuristic separate from Jev is a useful design choice. Not every link needs a model call, and code still controls budget, stop conditions, exact matches, and browser errors. Jev handles judgment; the engine handles orchestration.
POC 2 — 15Min Math Quiz Solver
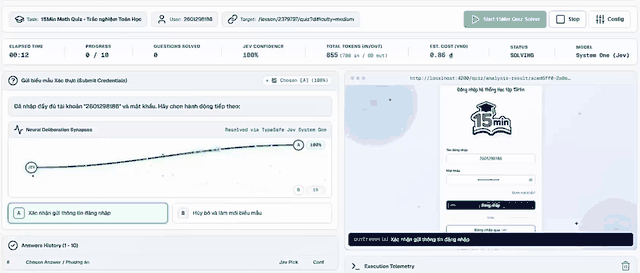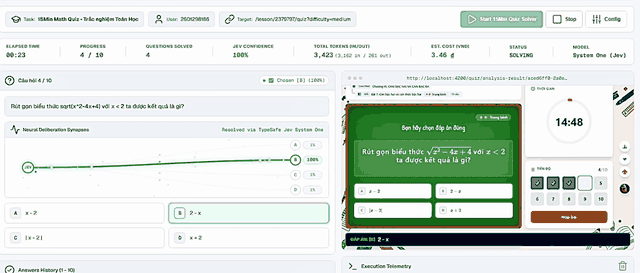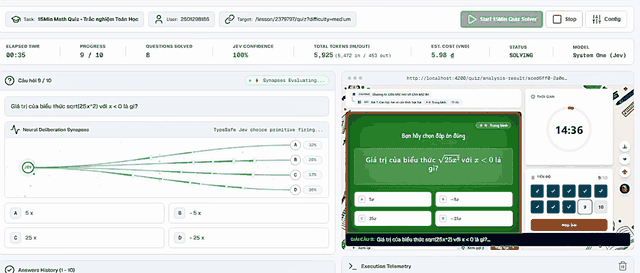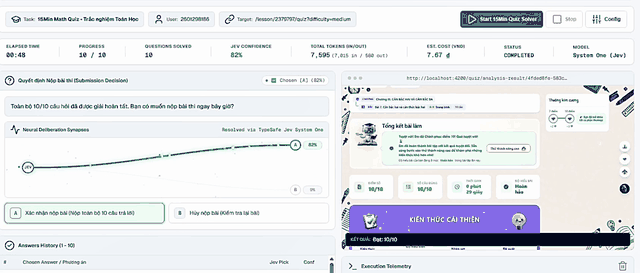
The second POC connects to a separate 15Min instance at http://localhost:4200. It is not a quiz-accuracy benchmark; it is a concrete trace of decision-in-the-loop automation: the runner reads the current question, constructs typed state, asks Jev to choose from a bounded answer set, and only then performs the browser action.
The default quiz URL in the repo is:
http://localhost:4200/lesson/2379791/quiz?difficulty=easyIn Settings, choose the quiz URL and use the local/test account provisioned for that environment. The defaults belong to the test environment; do not copy credentials that are still valid into a public article.
When started, Playwright signs in, opens the quiz, reads the question and choices, sends state to Jev, and clicks the answer selected by the engine. The value of the example is not automatic answer selection; it is the operational boundary it exposes. Execution authority, validation, auditability, retry limits, and escalation to human review must be defined by the system around the model.
Where should Jev sit in an AI system?
A sensible architecture does not choose between “only LLMs” and “only Jev”. Use each for the work it is good at:
User / event
    |
    v
State builder + policy context
    |
    +--> Jev: route, classify, score, gate
    |        |
    |        +--> typed decision + probabilities
    |
    +--> LLM: explain, plan, generate, synthesize
             |
             +--> draft / tool arguments / final response

Code owns: thresholds, permissions, retries, side effects, audit, and stop gates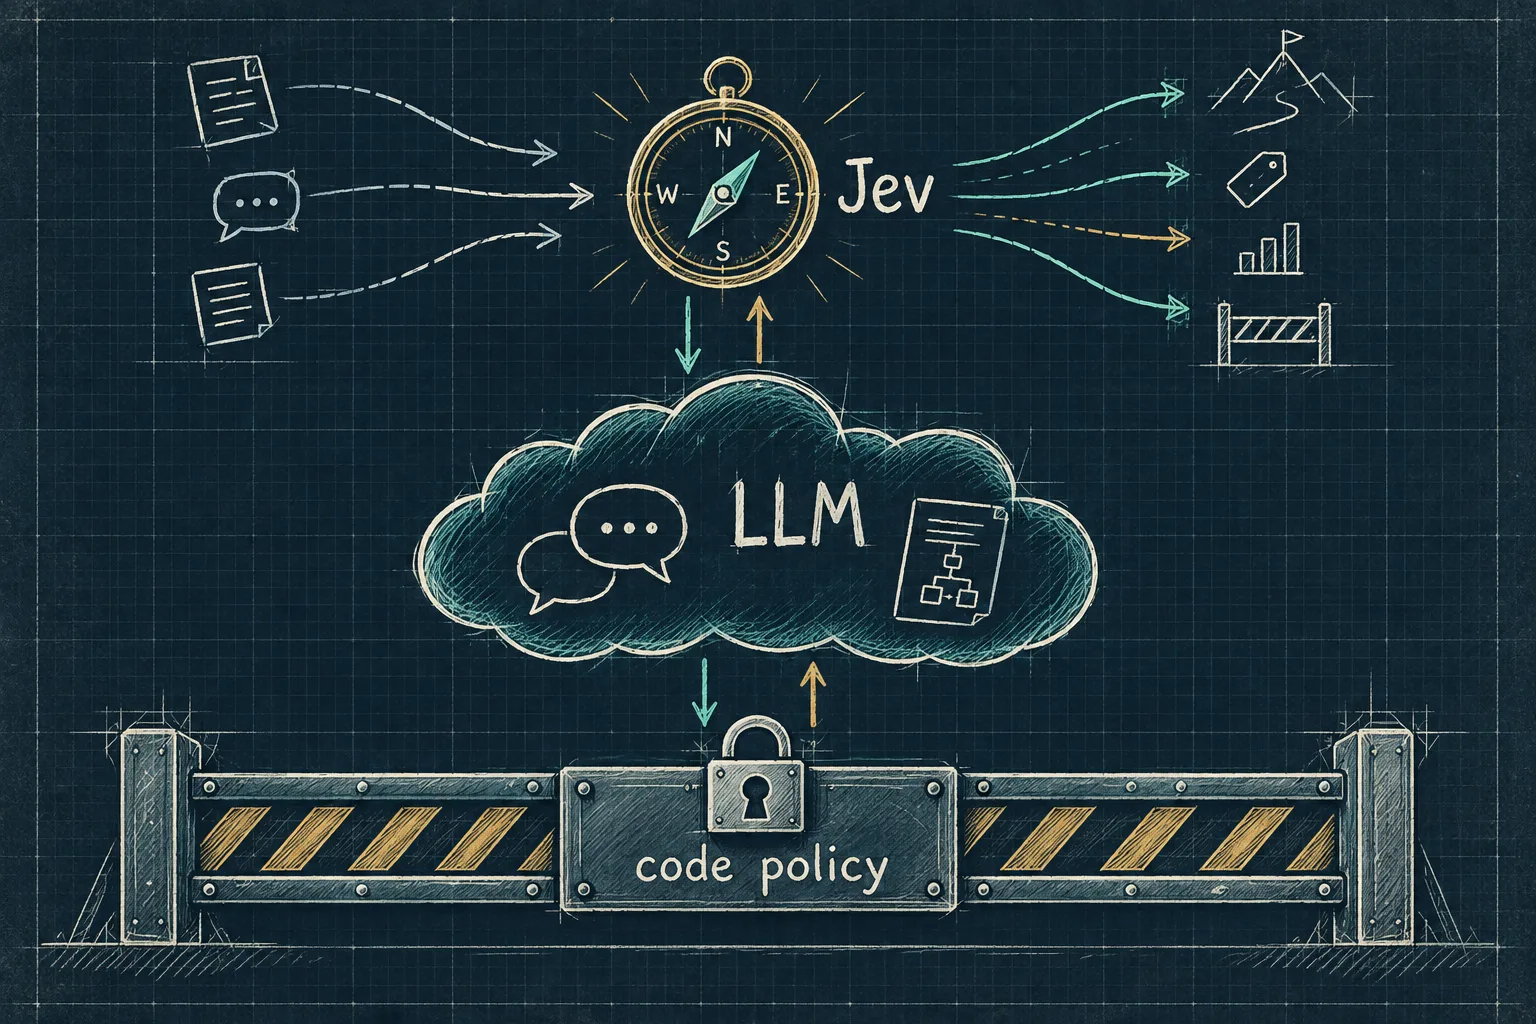
For example, Jev can decide whether a request should go to a fast or a frontier model, an LLM can write the response, and Jev can check a gate before a tool call. If confidence is low, code can escalate or ask a human; it should not silently turn a probability into execution authority.
Limits worth keeping in view
- Jev is a hosted model called through an API, not a local model bundled with the application.
- The demo passes text/data-structure state into the model; it is not a vision system reading browser pixels directly.
- Jev returns typed decisions, but it can still be wrong. Confidence is a policy signal, not a correctness certificate.
- It should not replace open-ended reasoning, long-form writing, or cases where the option space cannot be declared.
- Keep API keys in a server/session boundary. The demo’s API Key field is appropriate for local experiments, not a pattern to copy into a public production app.
The most interesting change is not the slogan “AI is faster”. It is the boundary. When the question is clear and the output space can be declared, a model does not need to pretend to be a person in a conversation. It can be a composable, observable, controllable evaluation primitive.
That makes Jev a good fit for the small but frequent judgments inside an agent: route a request, choose a tool, filter context, rank candidates, check a condition, or decide whether to escalate. It does not make a system safe simply by existing. It gives engineers a clearer primitive on which to place policy.
Comments (0)