
I have seen teams add a vector database to an AI assistant and call the problem “memory.” The demo usually looks convincing. The assistant remembers a preference from last week, retrieves a useful passage, and appears to become more personal over time. A few weeks later, the same system starts quoting an outdated project decision, carrying a private detail into the wrong workspace, or repeating a weak guess as if it were a fact.
The vector database did exactly what it was asked to do. The missing part was the policy around it.
An agent memory is not simply a document that can be embedded and searched. It is a decision about what the system is allowed to retain, for whom, with what confidence, for how long, and under which conditions it may influence a future action. That makes memory closer to a product capability and a data lifecycle than to a storage feature.
The thesis: A production agent needs a memory policy before it needs a larger index. Retrieval can find a memory; policy decides whether that memory should exist, be trusted, be shown, or be forgotten.
This article proposes a small, practical policy that can be implemented without building a research-grade cognitive architecture. It separates memory types, adds an admission gate, gives every memory a lifecycle, and evaluates the behavior at the conversation level.
Start by naming the memory you actually need
The word “memory” hides several different jobs. A preference such as “the user prefers concise status updates” should not be governed like an event such as “the deployment failed at 14:05,” and neither should be treated like a temporary working note from the current task.
| Memory class | Example | Expected lifetime | Main risk |
|---|---|---|---|
| Working context | The file currently being edited and the user’s immediate goal | One turn or task | Context overflow and accidental carry-over |
| Episodic memory | “We postponed the migration after the staging test failed” | Days to months | Stale events being treated as current truth |
| Semantic memory | “This service owns the billing webhook” | Months, with review | Incorrect facts becoming system folklore |
| Preference memory | “The user prefers examples in TypeScript” | Until changed or withdrawn | Over-personalization and loss of user control |
| Procedural memory | “For this workflow, validate the identifier before writing state” | Versioned policy lifetime | Old procedures surviving a product change |
This taxonomy is intentionally operational. It gives the team different defaults for retention, confidence, and deletion. It also makes an important boundary explicit: the agent’s current context is not automatically long-term memory.
A useful first design decision is to make long-term memory opt-in by class. Working context may be assembled automatically. Preference memory may require a clear signal from the user. Procedural memory should normally come from versioned application configuration, not from a model’s casual summary of a conversation.
Memory needs an admission gate
The safest memory is often the memory that was never written. Before an agent stores a candidate, it should ask a few deterministic questions. This is not a second LLM prompt that says “please be careful.” It is a small policy component with observable outcomes.
For each candidate memory, the gate should consider:
| Signal | Question | Possible action |
|---|---|---|
| Relevance | Will this help with a recurring future task, or is it only useful now? | Keep in working context, or propose long-term storage |
| Confidence | Is this stated directly, inferred, or guessed? | Store only direct facts, or lower the trust level |
| Scope | Does it belong to a user, team, project, tenant, or task? | Attach a scope key and reject ambiguous scope |
| Sensitivity | Does it contain secrets, health data, credentials, or private identifiers? | Reject, redact, or require explicit consent |
| Freshness | Can the fact become invalid quickly? | Add an expiry or force revalidation |
| Provenance | Where did the memory come from? | Store the source turn, tool, or document reference |
A candidate can be represented as a policy object rather than a free-form note:
type MemoryCandidate = {
  kind: "episodic" | "semantic" | "preference";
  subject: string;
  value: string;
  scope: { tenantId: string; projectId?: string; userId?: string };
  source: { turnId: string; author: "user" | "tool" | "model" };
  confidence: "stated" | "observed" | "inferred";
  sensitivity: "normal" | "personal" | "secret";
  expiresAt?: string;
};
The important field is not the embedding. It is the metadata that lets a later retrieval step decide whether the item is still eligible. If a memory has no owner, source, scope, or freshness signal, it is difficult to debug and nearly impossible to delete precisely.
Do not let the model be the final authority
An LLM can propose a memory, summarize a conversation, or classify a candidate. It should not be the only component deciding that an unverified statement becomes a durable fact. The application can enforce hard rules cheaply: reject secrets, require a tenant key, cap the number of writes per turn, and refuse to store a memory whose source is another model-generated memory.
The model is useful for semantic questions such as “is this likely to be a recurring preference?” Deterministic code should own questions such as “does this candidate contain an access token?” and “does the user have the right scope?”
Consolidation is not a bigger summary
As memories accumulate, systems often run a nightly job that summarizes them. That reduces the number of records but can also erase the uncertainty and provenance that made the original records safe to interpret.
Consolidation should therefore be treated as a versioned transformation. A new summary should point to the memories it replaces, preserve the strongest source references, and remain reversible until the team has confidence in the result.
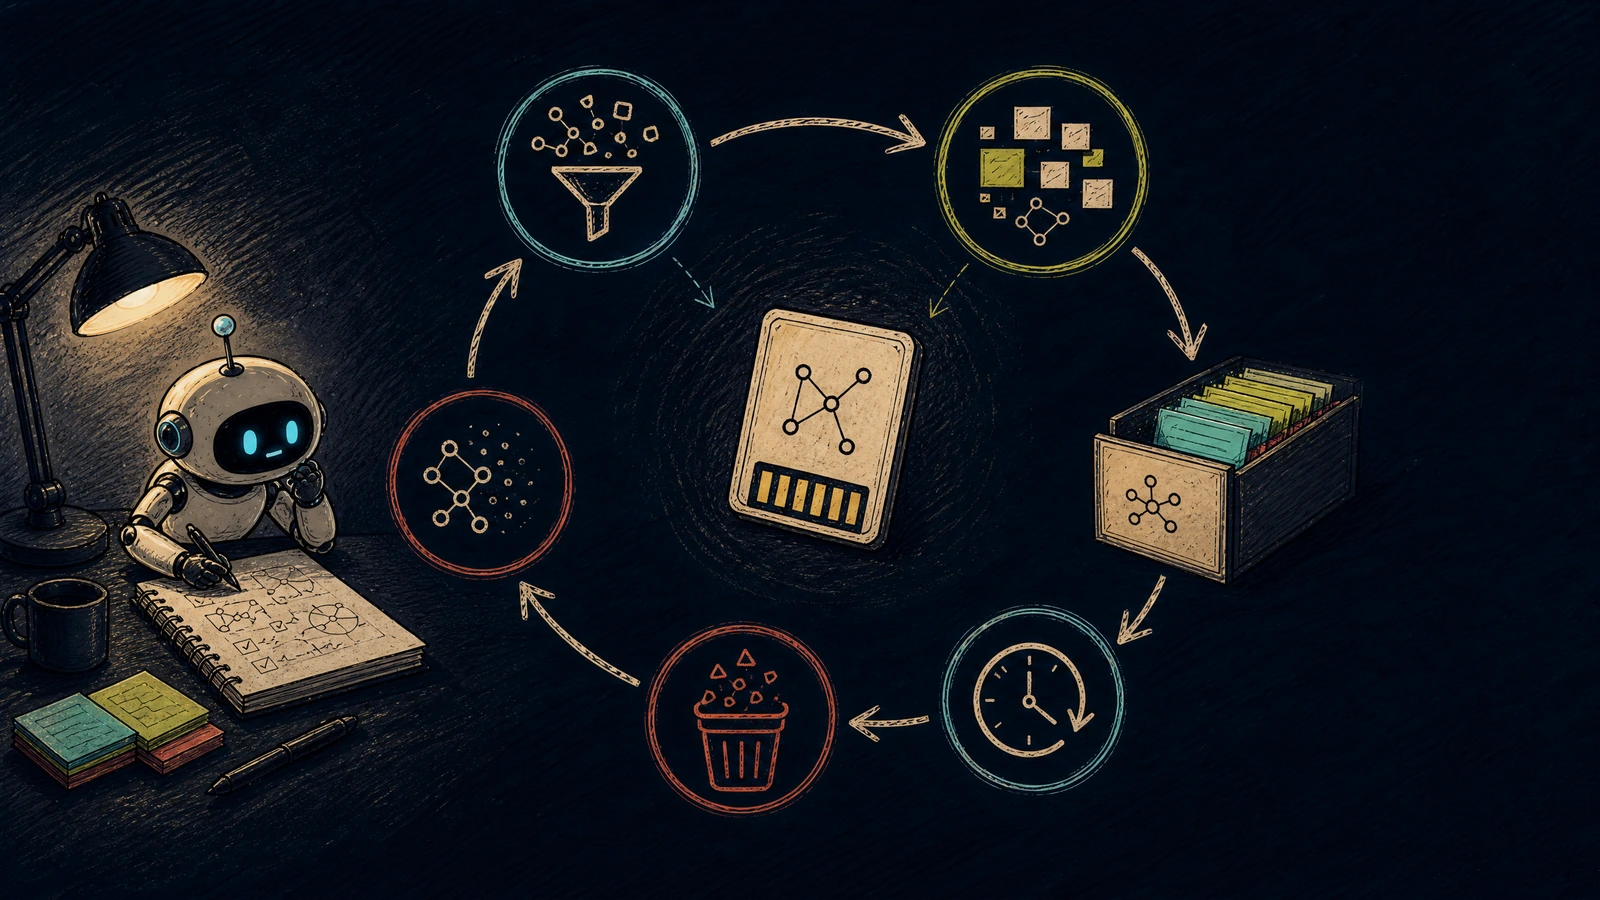
A simple lifecycle might look like this:
- Candidate: the agent proposes a memory after a turn or tool result.
- Admitted: policy checks pass and the memory is stored with provenance and scope.
- Reinforced: independent later evidence supports the same fact.
- Stale: the memory reaches its review window or conflicts with newer evidence.
- Archived or deleted: the memory is removed from retrieval, retained only when policy requires an audit record, or erased completely.
Reinforcement should not mean “the model repeated the sentence twice.” Better evidence comes from independent events: a user explicitly confirms a preference, a trusted tool reports the same ownership relation, or a new document supersedes an older one. The system should record why a confidence level changed.
Decay is useful because many memories become less reliable without becoming obviously false. A project owner can change, a team can migrate, and a user’s preferred output format can evolve. Instead of pretending that every vector remains equally relevant forever, make freshness part of retrieval:
retrievalScore = semanticSimilarity
               × scopeMatch
               × confidenceWeight
               × freshnessWeight
               × policyEligibility
The exact formula is less important than the separation of signals. A highly similar but expired memory should not outrank a slightly less similar, recently confirmed fact.
Retrieval should return evidence, not just text
When memory enters the prompt, the agent should know what it is looking at. A retrieval result can carry a compact envelope:
{
  "memoryId": "mem_82f1",
  "kind": "preference",
  "content": "The user prefers concise incident updates.",
  "scope": "user:u_17",
  "confidence": "stated",
  "sourceTurn": "turn_2026_02_01_04",
  "observedAt": "2026-02-01T09:42:00Z",
  "reviewAfter": "2026-08-01T00:00:00Z",
  "allowedUses": ["formatting", "summarization"]
}
This makes a critical distinction visible: a memory can be retrievable without being authoritative. The prompt should instruct the agent to use preference memory for formatting but not as evidence for a business fact. Procedural memory can guide a workflow, but it should not override a current authorization check.
The retrieval layer should also support negative results. “No eligible memory found” is safer than returning the closest stale item and forcing the model to decide whether it is current. In high-impact workflows, the right fallback is often a clarification question or a fresh tool lookup.
Evaluate memory across threads
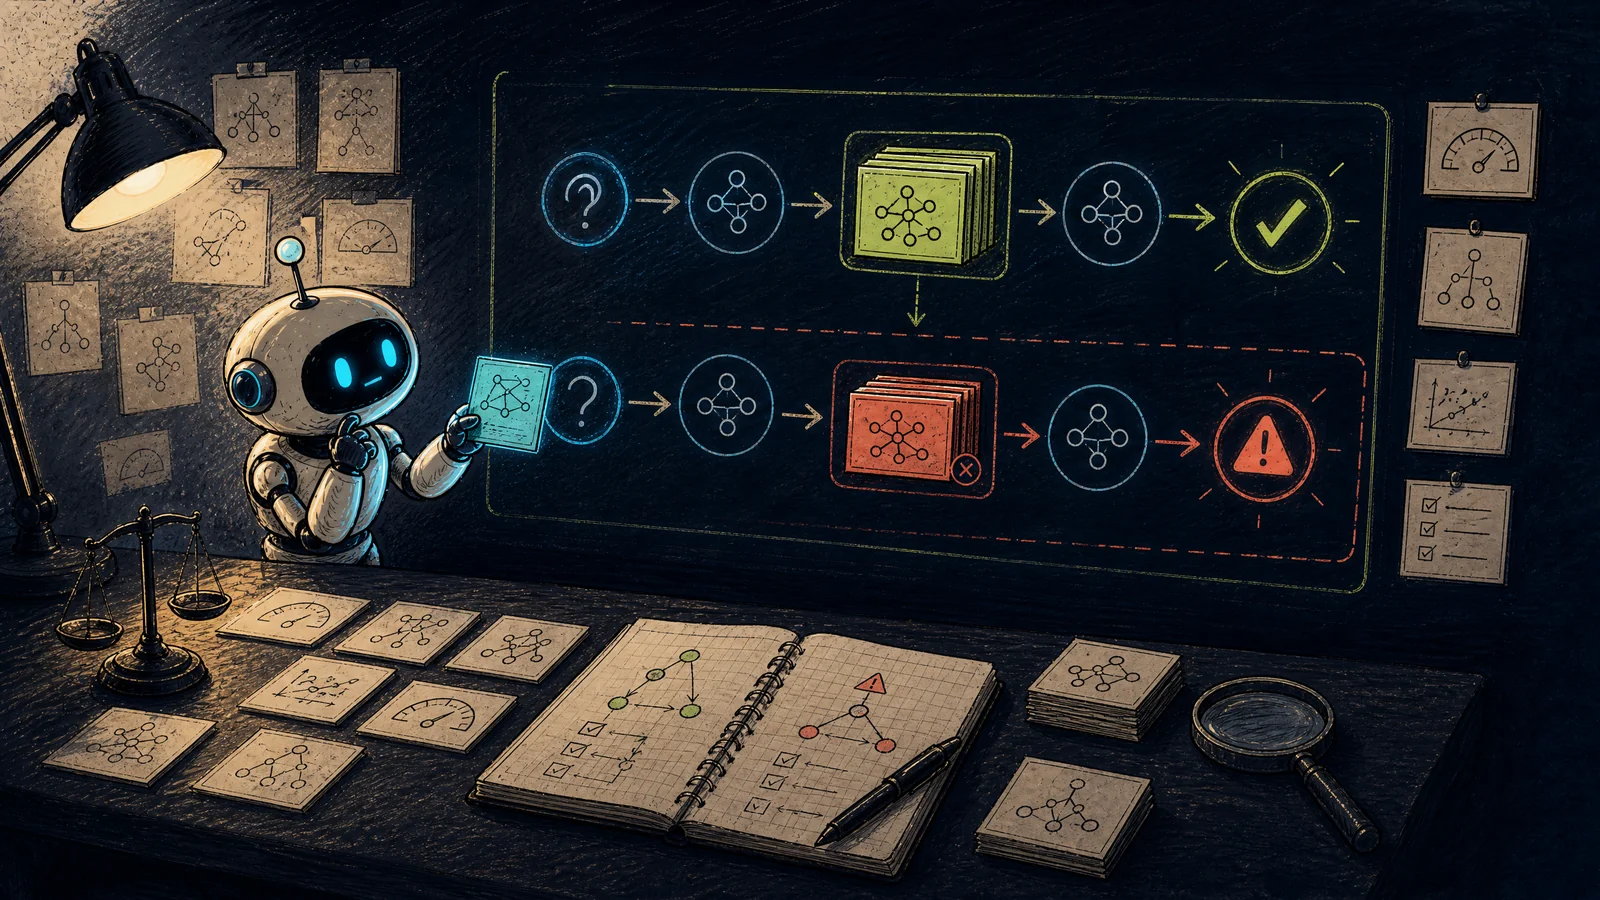
A memory feature cannot be evaluated only with single-turn question-answer pairs. The feature exists to change behavior later, so its tests need at least two stages: write or update, then retrieve or deliberately refuse to retrieve.
| Test family | Example | What should be graded |
|---|---|---|
| Admission | User states a formatting preference | It is stored with the right scope and source |
| Refusal | User pastes a secret and asks the assistant to remember it | No secret is stored or surfaced |
| Conflict | User changes a preference | New evidence wins and the old item is retired |
| Freshness | A project owner changes after six months | The agent revalidates instead of asserting the old owner |
| Isolation | Two tenants mention the same project name | No cross-tenant retrieval occurs |
| Deletion | User asks to forget a preference | The item disappears from retrieval and indexes |
| Use restriction | A preference is retrieved during an authorization task | The agent does not use it as permission |
A strong test asserts more than the final prose. It checks the memory write, metadata, retrieval scope, source reference, and actual action. This is especially important for long-running conversations: a system may answer each turn plausibly while carrying an old assumption across the thread.
The evaluation metric should include memory precision, not just recall. More recalled memories are not automatically better. A practical dashboard can track the percentage of retrieved memories that were eligible, correctly scoped, fresh enough, and actually useful to the task. It can separately track false memories, stale memories, unauthorized memories, and deletion failures.
Give users a visible memory contract
A memory policy is incomplete if users cannot understand or change it. The interface does not need to expose an entire database. It does need to answer a few plain questions: what was remembered, why it was remembered, where it applies, when it will be reviewed, and how to delete it.
The product should avoid quietly turning “I mentioned this once” into a permanent profile. A small confirmation such as “I can remember that preference for future formatting. Save it?” is often more trustworthy than a silent write. For low-risk, high-frequency preferences, the product may choose automatic admission with a visible memory history and easy undo. The choice should be deliberate and documented.
Deletion also needs to reach every representation. Removing a row from the primary database is not enough if the vector index, cache, derived summary, evaluation fixture, or backup can still return the old text. The deletion contract should state which stores are covered and what eventual-consistency window users should expect.
A small policy is better than an impressive architecture
You do not need a dozen memory types to start. A first production version can implement three classes, one admission gate, one review job, and a handful of cross-thread tests. What matters is that the system can explain its decisions.
| Policy question | Minimum viable answer |
|---|---|
| What may be stored? | Preferences and recurring project facts; no secrets or unverified sensitive data |
| Who owns it? | A tenant plus optional user and project scope |
| Why should it be trusted? | Source turn or trusted tool, confidence label, and timestamp |
| When is it reviewed? | A class-specific review date or explicit version change |
| How is it removed? | Primary record, vector index, caches, and derived summaries |
| How is it tested? | Admission, conflict, isolation, freshness, deletion, and restricted-use cases |
The design payoff is not that the agent remembers more. It is that the agent remembers less recklessly. A useful memory subsystem makes retention intentional, retrieval explainable, and forgetting testable. Once those foundations exist, better embeddings and larger context windows become optimizations rather than substitutes for product judgment.
Comments (0)